Gradient descent is the workhorse of machine learning, and it has a well-known
weakness. On a long, narrow valley it bounces from wall to wall while creeping
along the floor. Adding momentum, a running memory of past gradients, is a
one-line change that often makes it several times faster. This article shows why,
on the simplest valley there is.
Its gradient is ∇f(w)=(λ1w1,λ2w2), and the ratio
κ=λ2/λ1=10, the condition number, measures how
narrow the valley is. Plain gradient descent takes steps of size α:
wk+1=wk−α∇f(wk).
A step large enough to make progress along the shallow direction overshoots in
the steep one, and a step small enough for the steep one crawls along the
shallow one. The best fixed step, α=2/(λ1+λ2), shrinks the
error by a factor of (κ−1)/(κ+1)≈0.82 per step.
Momentum keeps a velocity z that accumulates gradients and decays by a factor
β each step:
zk+1=βzk+∇f(wk),wk+1=wk−αzk+1.
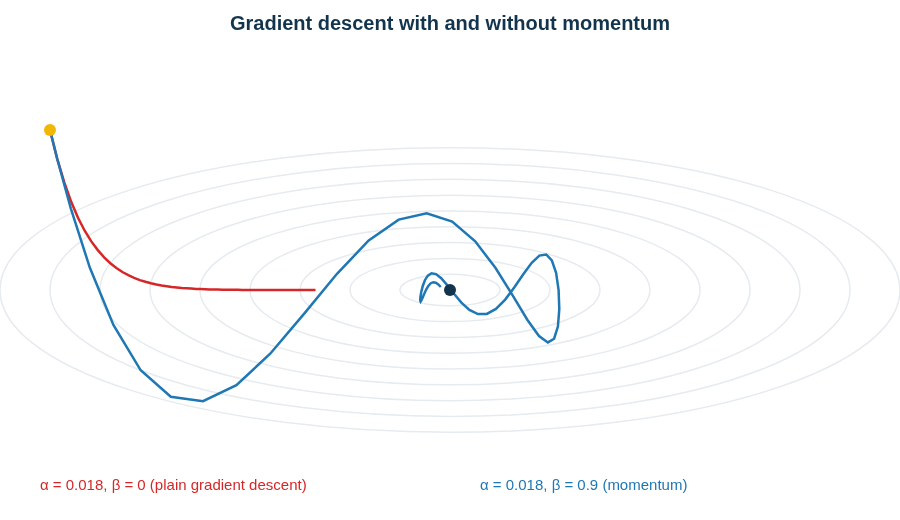
Oscillations across the valley point in alternating directions and cancel in
z; the small, consistent pull along the floor adds up. With the best choice of
α and β the error shrinks by (κ−1)/(κ+1)≈0.52
per step: about 11 steps instead of 35 to reduce it a thousandfold.
Gradient descent without momentum (red) and with it (blue), on the valley above. With JavaScript, this figure has sliders for the step size and momentum.
This sample follows the style of Distill articles and borrows its example from
Gabriel Goh’s Why Momentum Really Works,
which analyses the same valley in far more depth.